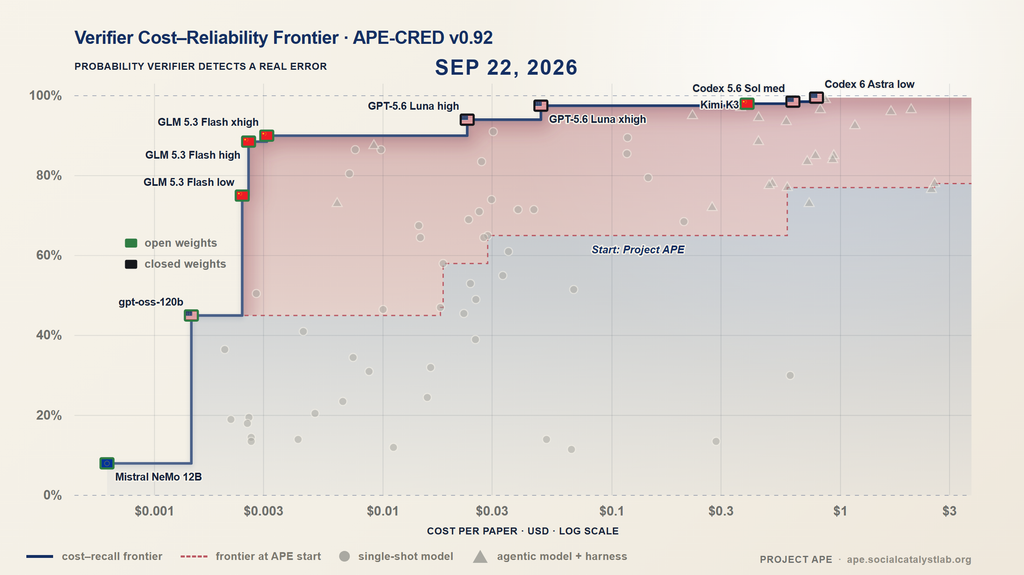
This is a lovely visualisation from Project APE at the University of Zurich’s Social Catalyst Lab, tracking how good AI verifiers are at finding deliberately planted errors in AI-generated research papers, and how much it costs to find them. Models released over the past 18 months went from finding about 4 in 10 errors to finding almost all of them, while the cost of finding roughly three-quarters of the errors fell about 1,000×, from $2.50 per paper for a model released in August 2025 to $0.0025 with the latest models.
Figures below are read from the chart:
- April 2025: The best-performing verifier, DeepSeek R1, found 39% of the errors for $0.025 per paper.
- August 2025: The best performer, an agentic setup using Opus 4 high, found 77% of the errors for $2.50.
- February 2026: Agentic setups using Sonnet 4.5 high and Opus 4.1 high found 77% of the errors for $0.60 and 78% for $2.60.
- September 2026: The best performers, agentic setups using Codex models, found almost all the errors for less than $1 per paper. A low-cost model, GLM 5.3 Flash, found 90% for $0.003 at its highest reasoning setting.
Older working paper: https://ape.socialcatalystlab.org/cred/verifying-the-verifiers.pdf