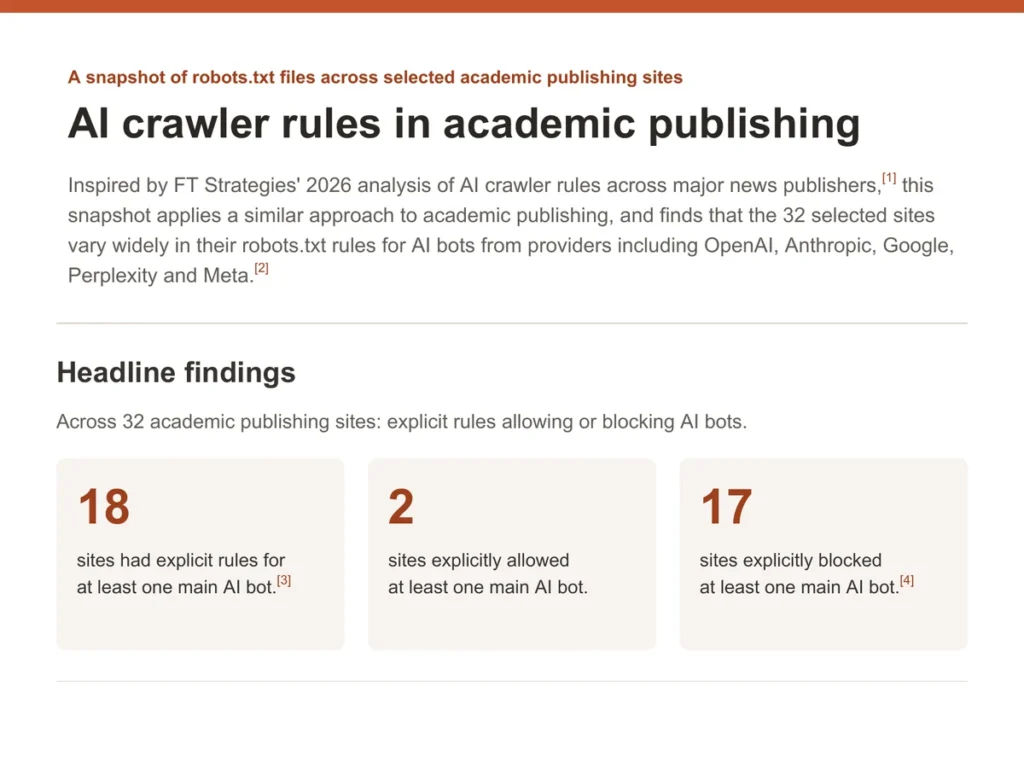
I put together this snapshot of AI crawler rules in the robots.txt files of 32 academic publishing sites after reading FT Strategies’ analysis of news publishers’ robots.txt files. Only afterwards did I realise that it has limited value, because services such as Cloudflare can block AI bots at the network level without anything appearing in robots.txt, so the snapshot shows publishers’ stated positions rather than what AI crawlers can actually reach.
What academic publishers’ robots.txt files say about AI crawlers